TOP sets down his empty cup beside a ticket from the internal Coffee Break app: its reorder button returned an error. The office coffee point has run out of beans. He opens the application on his laptop and takes ownership of the incident: first separate the menu read from the durable order path, then find where the failure begins.
At reception, a colleague shows him Coffee Break, a small internal app for checking current menu and submit a restock order. The beans are out, and the order button fails. TOP writes down his first question: “What can this app really tell me?”
That is our starting point for this revised five-part VKS series. TOP Dev follows the software’s needs, using infrastructure knowledge to explain what happens when an application leaves its developer’s machine. As in Works on my machine, we start with a useful request; this time Coffee Break supplies the story. The internal application already exists: the exercises isolate its mechanisms, without building a whole platform during this incident. The aim is a working, observable service with known owners.
This article was substantially revised on 27 October 2026. It covers the VCF 9 family and vSphere Kubernetes Service, abbreviated VKS. Specific APIs, supported releases and consumption interfaces depend on the installed environment. The examples are explained exercises, with no claim of having deployed this series on a real VKS platform.
Start with the request, then draw the platform
Coffee Break has two distinct operations: GET /menu reads stock; POST /orders records a replenishment request. An accepted order returns 201 Created and an identifier the front end can retrieve with GET /orders/{id}. API processes use shared PostgreSQL: replacing a Pod must not erase order history. Recording a request neither increases physical stock nor prepares coffee.
Two exercises make these mechanisms observable. The Kubernetes fixture returns a fixed menu without a database or writes, isolating the Service path. The Coffee Break local lab adds a front end, an API and PostgreSQL. We checked creation, readback, retries with the same key and an order remaining readable after restarting the app and switching to v2. This local test is not a VKS execution.
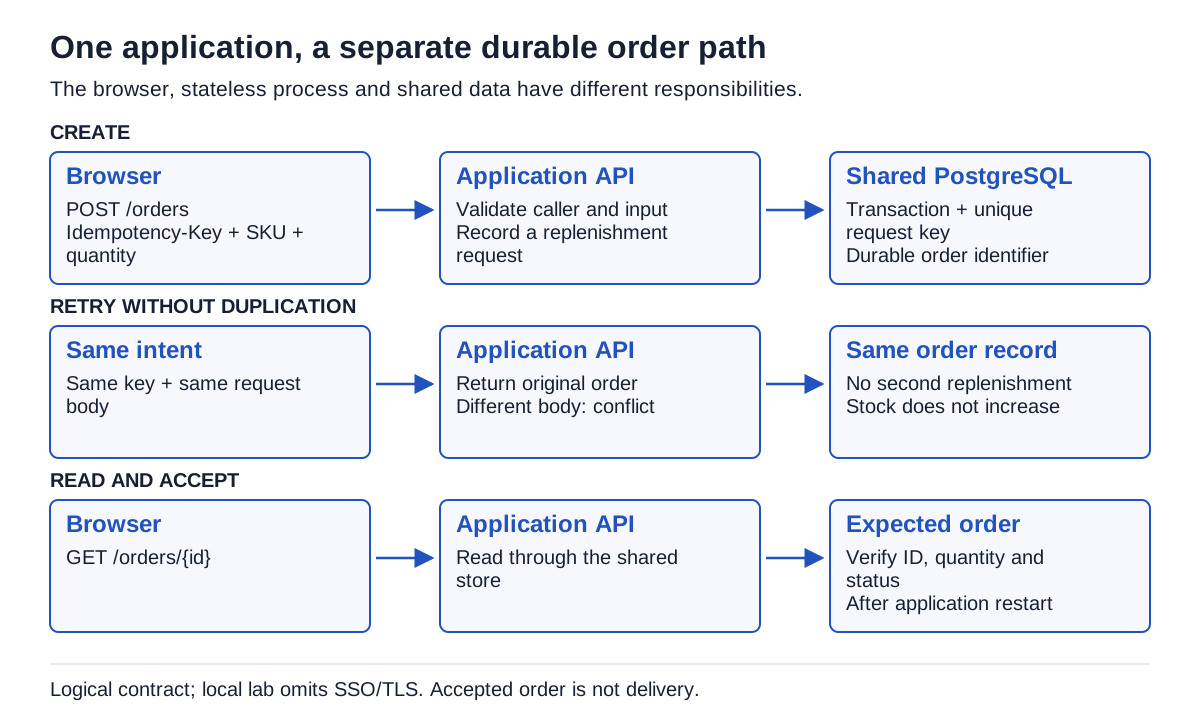
Creation, retry and readback form a testable contract. The local lab supplies neither SSO nor TLS; production must provide identity, authorization and trust through its approved integration.
The application needs an image, configuration, resources and usable network paths. Production also needs a narrowly scoped database identity, a secret kept out of Git, rotation and a recovery owner. The lab initializes its schema at startup; it does not demonstrate production migrations or permission management. Kubernetes can run the process correctly while the order still fails.
Before requesting a cluster, TOP writes a small execution contract:
| Question | Menu example | Evidence to collect |
|---|---|---|
| What runs? | A reviewed image identified by digest | Image actually used by the Pod |
| What must answer? | HTTP GET /menu and the separate order API |
Expected stock and a durable order identifier |
| What persists? | Orders and stock in shared PostgreSQL for the reference app | Data owner, scoped database identity and restore procedure |
| Who may connect? | User identity and application database role | Allowed operation under the intended identity |
| What must be reached? | Registry, DNS, database and user entry point | Tests from the relevant execution contexts |
| Who acts on failure? | App team with a platform escalation path | Named owner, alert and useful diagnostic data |
These are examples to decide together. They are not default VKS configuration. A company may provide a shared cluster and an application namespace instead of giving every team a new cluster. The contract still applies.
Two Kubernetes APIs, two kinds of desired state
The Supervisor exposes the management side used to provision VKS workload clusters. Its control plane includes dedicated Supervisor control-plane VMs; it is not simply the vCenter API renamed. Broadcom describes those VMs in KB 323407.
The workload cluster has its own Kubernetes API and control plane. This is where our team creates application Deployments, Services and ConfigMaps. A healthy workload API and an available management service are separate observations. A Supervisor incident does not automatically mean every running application process has stopped; the affected provisioning and lifecycle operations still matter.
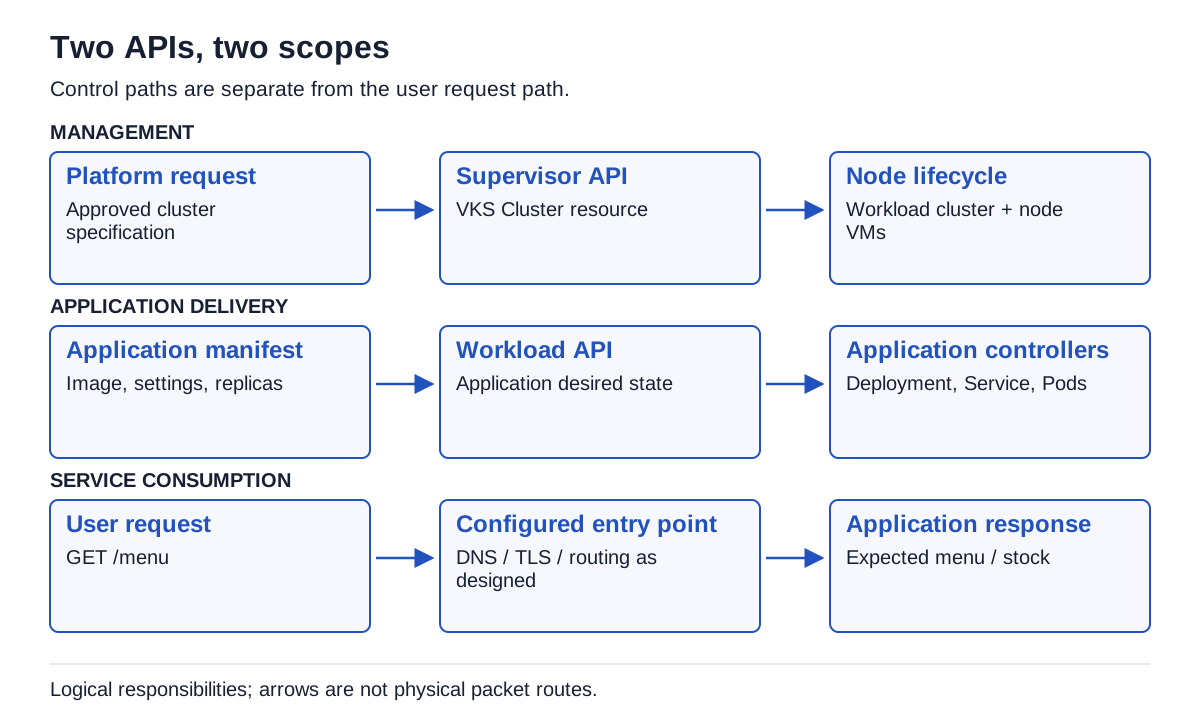
Two control paths and an application request path. Arrows show responsibilities, not physical packet routing.
A Cluster resource on the Supervisor describes a cluster to reconcile. A Deployment inside that cluster describes application replicas to reconcile. Both are declarative objects. They instruct different controllers, in different scopes, to produce different things. The Kubernetes component overview explains the workload API, scheduler and node responsibilities.
This distinction explains a practical mistake: applying an application manifest while still connected to the Supervisor. A valid YAML file can target the wrong system. Record both kubeconfig contexts and keep the context explicit in commands. A context is a local client configuration selecting a cluster and credentials; its friendly name alone is not proof of the destination.
At their desk, TOP and his colleague draw the order path on paper and divide the responsibilities: the platform team provides the boundary, while the application team specifies its process, permissions and data. The sketch becomes a list of testable questions.
A namespace has a scope, not a universal meaning
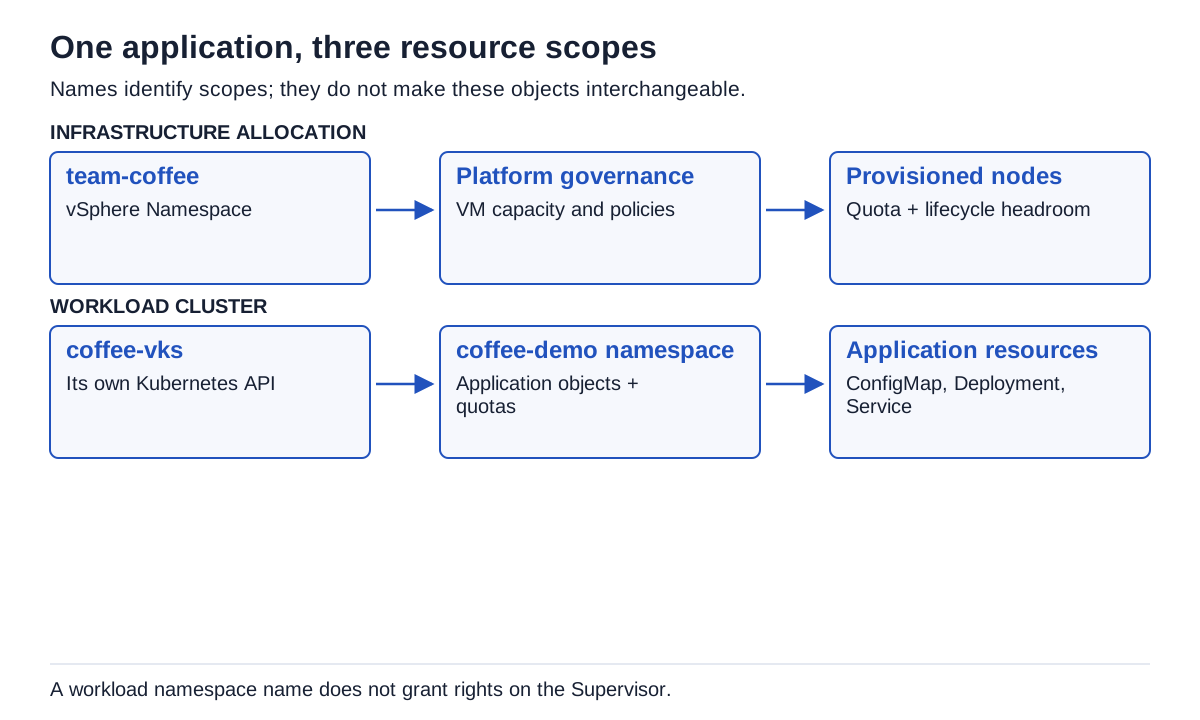
On the management side, a vSphere Namespace gives a team a governed area for its allocated infrastructure resources. Inside the workload cluster, a Kubernetes namespace groups namespaced application objects. Identical names would not make them the same object.
For this journey, we use team-coffee for the management allocation and coffee-demo for the application’s disposable exercise. The workload cluster is called coffee-vks. Those names deliberately differ so a screenshot or command cannot blur their roles.
A namespace also does not solve every isolation requirement. The required separation depends on Kubernetes RBAC, admission policy, workload security, networking and the trust between teams. A dedicated cluster may be justified; a separate namespace may be enough for another service. The platform team should publish that boundary rather than letting application authors infer it from a name.
TOP asks for two resource envelopes. The first covers the node VMs and spare capacity during lifecycle operations. The second covers application requests, limits and quotas inside the workload cluster. Free memory visible on a host does not prove either envelope admits the next Pod or replacement node.
Translate familiar infrastructure into application capabilities
Compute, storage and networking still exist underneath VKS. The application consumes their published capabilities through Kubernetes objects and platform interfaces. The translation is where useful collaboration happens.
An image registry stores the executable artifact. The runtime must reach it and trust it; a successful pull from the administrator’s laptop does not establish that the nodes can pull it. A ConfigMap can hold non-sensitive settings. A Kubernetes Secret needs an agreed protection and delivery model; its name does not make the application credential available or correct.
For persistent data, a PersistentVolumeClaim requests storage through a StorageClass. The application’s data lifecycle must account for the backing system and reclaim policy. Deleting and recreating a Pod is not the same operation as restoring its data. See Persistent Volumes.
For exposure, a Service provides a Kubernetes service abstraction. External access requires the platform’s supported load-balancing and, where used, HTTP routing, DNS and certificate arrangement. VKS does not give every application a public URL merely because its Pod is Running. Service types describe the Kubernetes side; the actual provider must be identified in the environment.
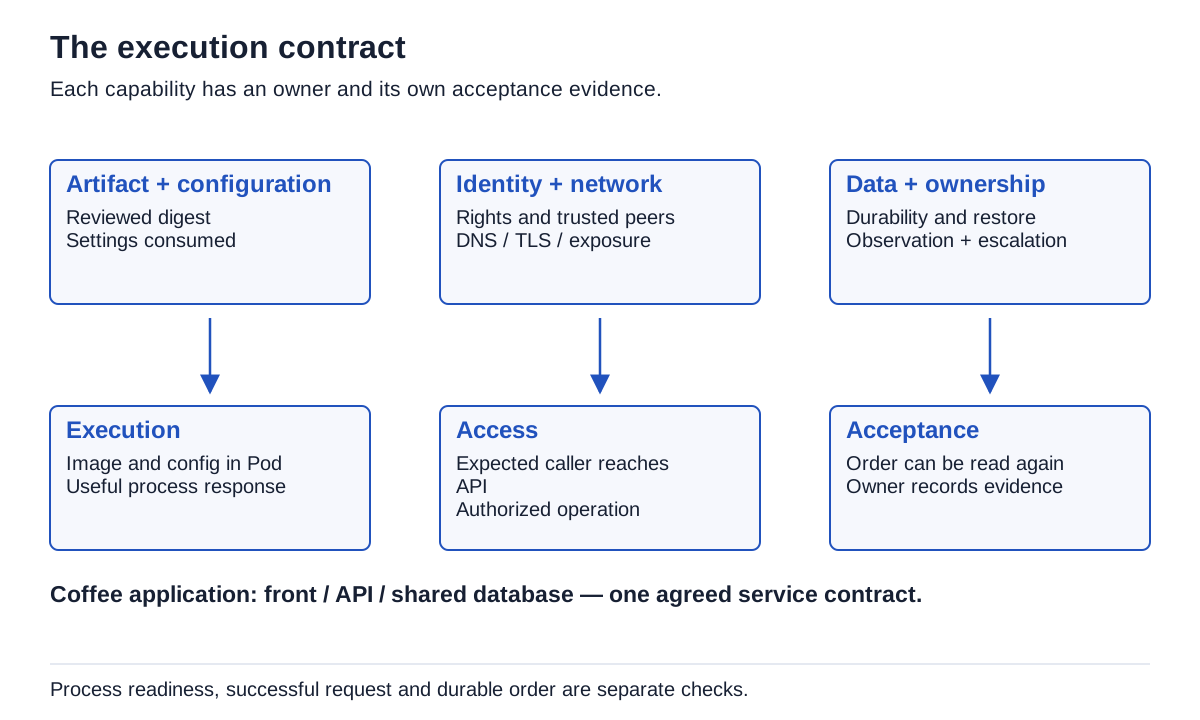
Each capability has an owner and an acceptance check. This is a service contract, not a product bill of materials.
Choose a consumption path without changing the responsibilities
A platform may expose approved cluster creation through a portal, a catalog or a Kubernetes/API workflow. VCF Automation can add organizational governance and self-service. Other environments expose a supported Supervisor workflow directly. Use the interface your platform operates and supports, with its approved template and identity model. VKS management guide.
The important output is concrete: target endpoint, issued credentials, allocated namespace, supported release, network exposure model, storage capabilities and support ownership. The number of clicks is a poor substitute for that handover. A generated manifest is worth reviewing; generation does not make its sizing or policies appropriate for production.
Record the three levels before selecting releases:
| Level | What to record | What to check |
|---|---|---|
| Platform and Supervisor | Actual installed release | Compatibility with VKS and management components |
| VKS service | Installed service release | Offered Kubernetes releases and supported route conditions |
| Workload cluster | Current and target Kubernetes release | Supported combinations and compatible add-ons |
Their lifecycles can be separated within supported combinations. Before a change, consult the interoperability matrix and release notes for the actual source and target. Broadcom’s compatibility workflow makes that prerequisite explicit.
This journey concentrates on the architecture needed to deliver the menu service. A product upgrade design still needs its own build-specific assessment; an application coffee breakthrough cannot replace it.
The handover that lets us continue
Before moving on, TOP checks that the team can identify the two API endpoints, explain its identities, locate the allocated namespaces and describe one useful request. He also asks what happens when its current application process disappears: which controller replaces it, where its configuration comes from, and where its data remains.
After the service is deployed, we will repeat the same request, from the intended user path, with the intended permissions. We will compare the actual image and configuration with the contract. These checks will be carried through maintenance and GitOps, rather than invented again at the end.
Leaving the coffee corner, TOP reviews the questions in his incident notebook with his colleague: the menu responds, but the order fails. They agree who will check each step between the APIs and the database before continuing the investigation through VKS.
Next, TOP follows the coffee point clue and examines the request path. Follow the network journey: Service, ready endpoints, external entry point and return path. The cartoon opens the investigation; the observations will tell us which layer needs attention.
Get the next one by email
New articles and series, sent when they are published. No other mail.